Start with evidence assembly and an owned incident record, not autonomous containment. An incident-response agent earns production authority only when every alert group retains provenance, every system write is reconciled and every material action has a named human boundary.
Jump to the cost worksheet if the workflow is already clear. This page is for a CTO, security engineering lead or platform operations owner scoping one pilot. It is an internal reference model, not a client result, vendor quote or promise that AI will reduce incident cost.
Choose one incident workflow
Start with one alert source, one incident system and one owned playbook family. The first pilot should group a bounded set of events, assemble a cited evidence packet, open or update the incident record and hand the packet to a named incident commander. Do not start with every signal in the security stack or a general instruction to resolve incidents.
Use this initial contract:
- Input: eligible alert groups from one named source, with stable event identifiers and source timestamps.
- Evidence: raw event references, correlation rules, enrichment results and the exact playbook version.
- Output: one incident packet plus a created or updated record in the sanctioned incident system.
- Owners: one workflow owner, one incident commander and one systems owner for the destination.
- Acceptance: the incident commander accepts the packet and the destination reads back the intended record state.
- Stop rule: missing provenance, contradictory evidence, out-of-scope targets and sensitive decisions leave the automated path.
NIST's final SP 800-61 revision 3, published in April 2025, integrates incident response across Cybersecurity Framework 2.0 risk management rather than treating response as an isolated technical step. NIST's accompanying revision notice says all six CSF functions play a role. That is a useful warning against buying an alert summarizer and calling the response workflow complete.
Keep five operational routes separate
Every eligible alert group should end in a named route. A single confidence score cannot express whether the issue is evidence quality, system state or decision authority.
- Enrich: current evidence supports a bounded incident packet. The agent retains source event IDs, a digest, the playbook version and every enrichment lookup.
- Act: a pre-scoped technical action has target-bound approval, a named rollback owner and an authoritative read-back plan. This route should not exist in the first pilot.
- Approval: the evidence supports a proposed action, but a person still owns the decision. The request identifies the exact target, intended effect, playbook and recovery path.
- Handoff: evidence is stale, conflicting or outside the contract. The incident commander receives the conflict intact and acknowledges ownership.
- Refuse: the request asks the agent to declare a breach, notify a regulator or customer, close the incident, delete evidence or take another prohibited action.
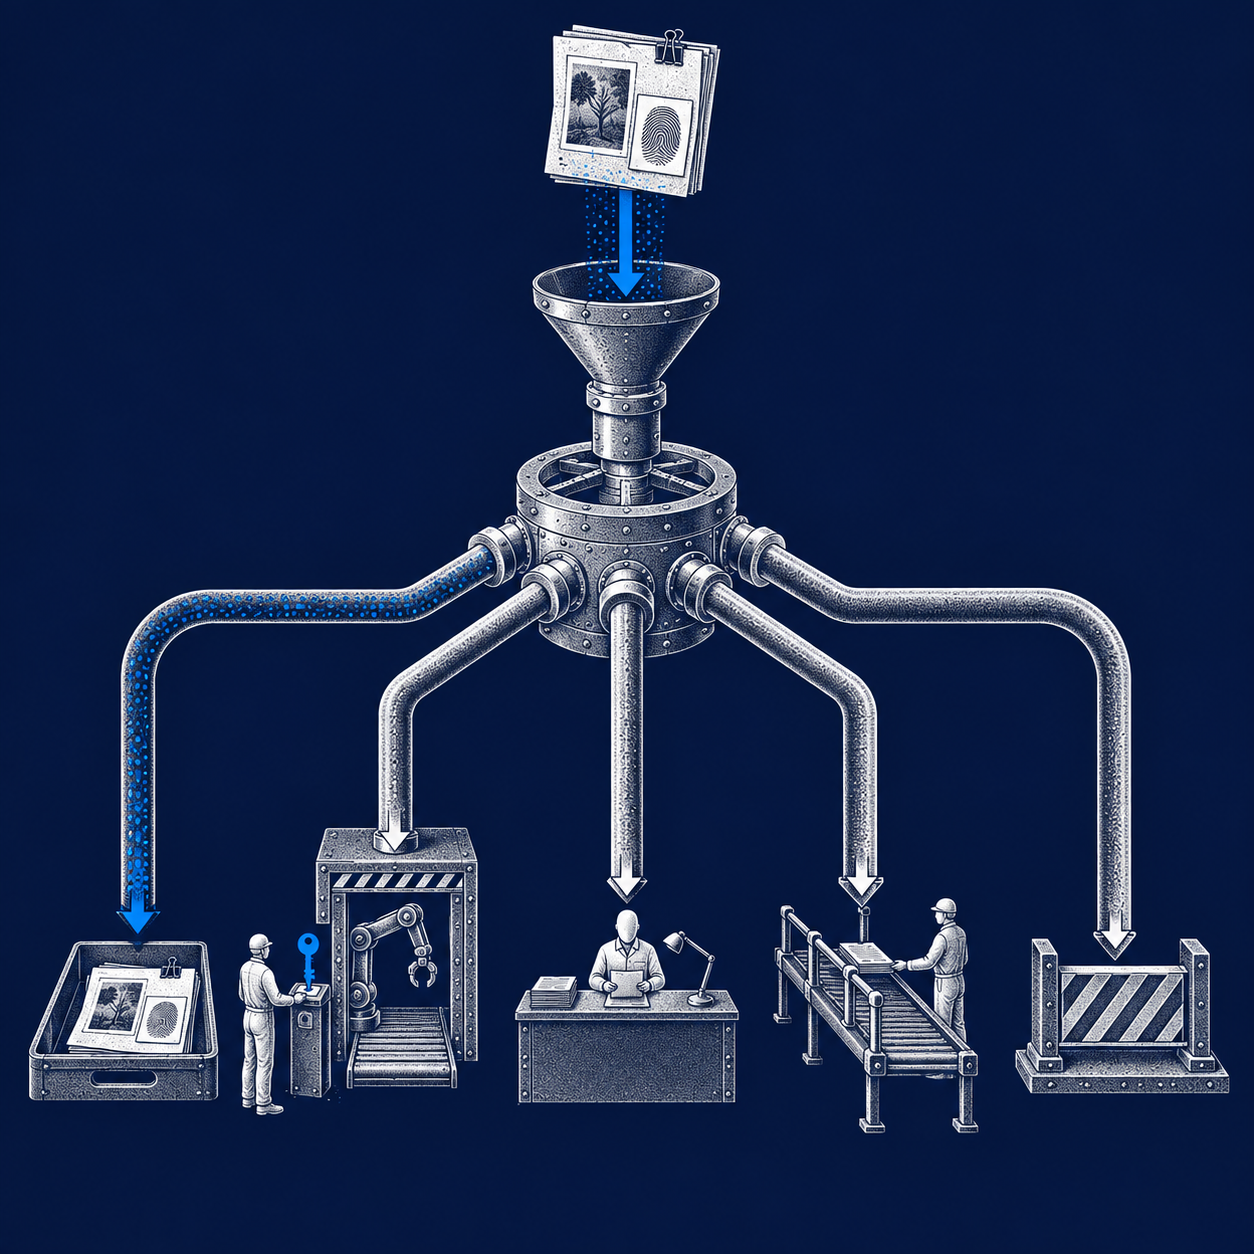
The distinction between approval and handoff matters. Approval means the proposal is sufficiently evidenced and needs accountable authorization. Handoff means the evidence boundary itself is unresolved. Refusal is not a low-confidence answer. It is a contract terminal.
This follows the same logic as a broader agent workflow operating contract: allowed actions, acceptance evidence, handoffs and stop cases are separate fields. A prompt does not supply any of them by implication.
Build an incident packet that survives review
The packet should make the decision reproducible without copying every raw event into the model context. Retain at least:
{
  "alert_group_id": "grp-2026-09-29-0042",
  "source_events": ["evt-8841", "evt-8848"],
  "evidence_digest": "sha256:example",
  "playbook": { "id": "account-access", "version": "3.1" },
  "target": { "type": "user", "id": "acct-17" },
  "proposed_route": "approval",
  "incident_commander": "security-on-call",
  "destination_record": "INC-2048",
  "reconciliation": "pending"
}
The digest binds the reviewed evidence set without pretending a summary is the source. The target prevents approval for one account, host or workload from being reused for another. The playbook version makes policy drift visible. The destination ID creates a place to read back authoritative state.
AWS's generative-AI-assisted incident-response architecture separates ingestion, processing, AI/ML, orchestration, storage and interface layers. Its guidance calls for comprehensive logging, defense in depth, graceful degradation, cost controls, ground-truth evaluation, human-led evaluation and operational simulations. The exact AWS design is not required here. The useful principle is that an agent summary is one layer in an inspectable operating system, not the operating system itself.
AWS also recommends a defined process for every alert, with clear ownership, escalation and current knowledge. Automated incident creation can link to a predefined response plan. That supports the narrow first workflow: make the record and its evidence reliable before expanding action authority.
Price accepted incident outcomes
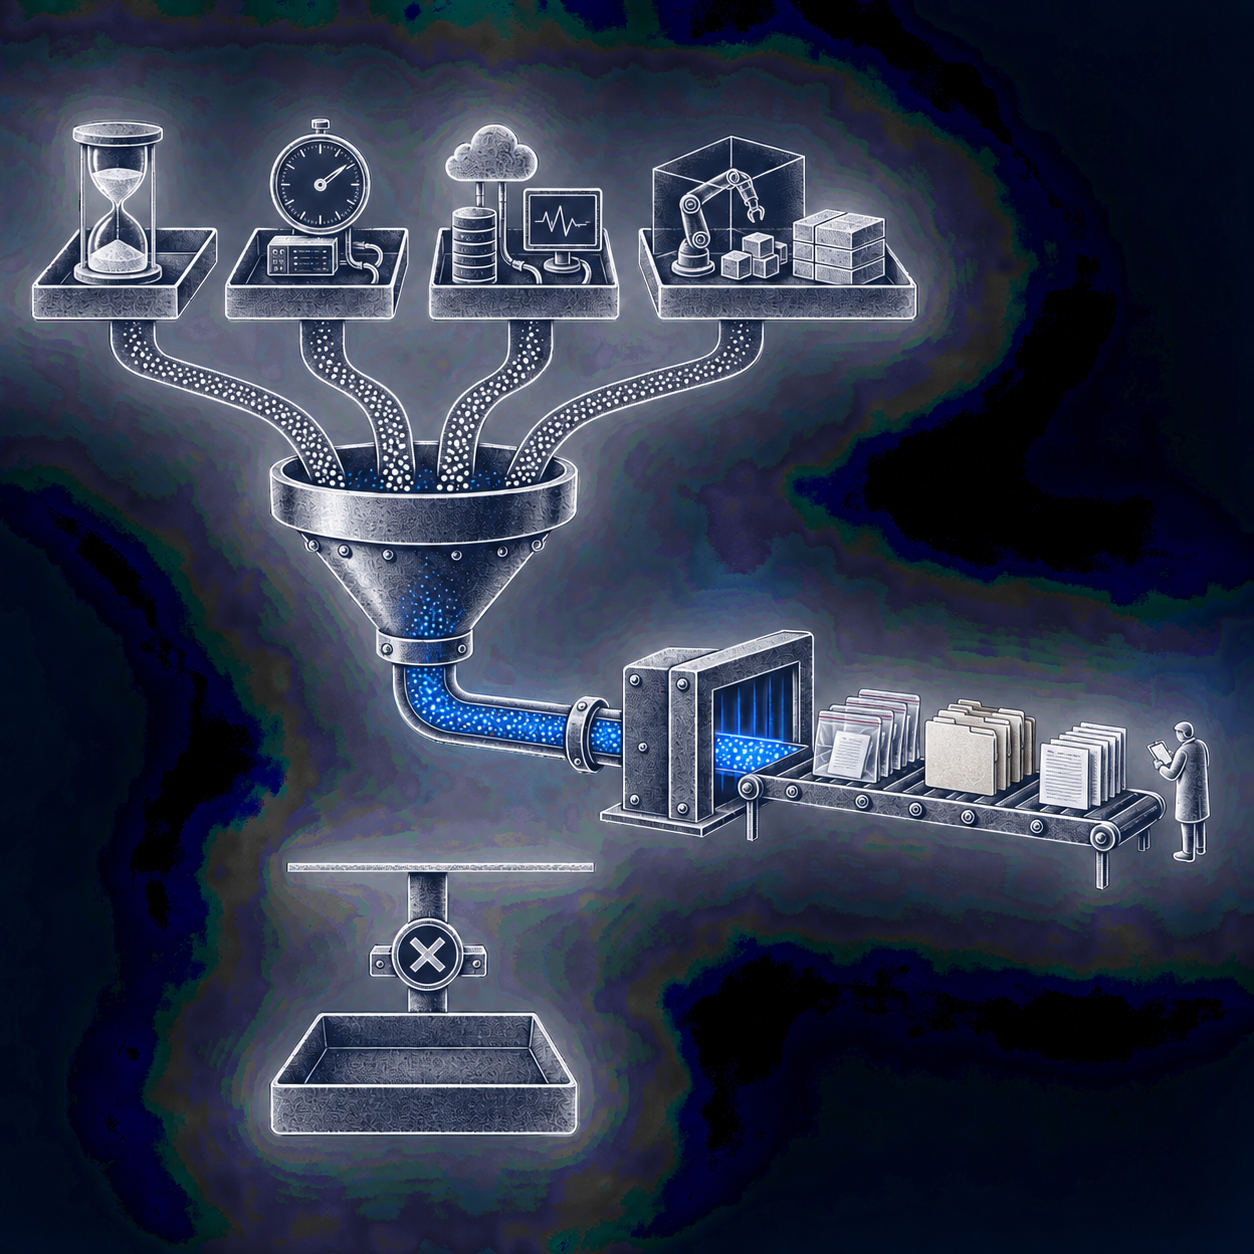
Measure one operating window. Raw alert count is not the denominator because deduplication and grouping determine the actual work unit. Start with eligible alert groups after the existing grouping rule, then preserve that rule and its version.
Use:
joined monthly cost = remaining human labor + runtime + integration and observability + simulations and review + amortized setup
Divide by accepted enrichment packets, reconciled incident records and acknowledged handoffs. Count each alert group once. If a group produces both an enrichment packet and an incident record, choose the terminal that represents the pilot's accepted unit instead of counting both.
Blank worksheet
| Input | Your value | Boundary |
|---|---|---|
| Eligible alert groups | Enter value | After one versioned grouping rule |
| Baseline human minutes per group | Enter value | Observed or explicitly modelled |
| Remaining human minutes per group | Enter value | Includes review and correction |
| Loaded hourly cost | Enter value | Reader-supplied planning assumption |
| Platform and runtime | Enter value | Observed invoice or allocation |
| Integration and observability | Enter value | Ingestion, destination, logs and monitors |
| Simulations and review | Enter value | Exercises, model review and playbook upkeep |
| Setup cost | Enter value | One-time build and release work |
| Amortization months | Enter value | Positive whole months |
| Accepted outcomes | Enter value | Reconciled and not double counted |
Synthetic arithmetic check
This fixture tests the worksheet. It is not a vendor price, industry benchmark, client result or savings forecast.
- 240 eligible alert groups in one month
- 18 baseline human minutes and 7 remaining human minutes per group
- $90 synthetic loaded hourly cost
- $450 platform/runtime, $600 integration/observability and $900 simulations/review
- $18,000 setup amortized over 12 months, or $1,500 for the month
- 120 accepted enrichment packets, 40 reconciled incident records and 20 acknowledged handoffs
Baseline labor is $6,480. Remaining labor is $2,520. Recurring technology and review cost is $1,950. Joined monthly cost, including amortized setup, is $5,970. The synthetic difference from baseline labor is $510. With 180 accepted outcomes, synthetic unit cost is $33.17.
Change remaining human time from 7 to 11 minutes and the same fixture becomes $7,410, which is $930 above the baseline labor model. That sensitivity is the point. A convincing demo can still fail the operating model when review and correction remain high.
If accepted outcomes are zero, unit cost is unavailable. Report that state directly. Do not turn a missing denominator into zero cost.
Run the reference controller
The retained reference is dependency-free. It does not connect to an alert source, decide whether an event is malicious or execute a real containment action. It proves that missing evidence and prohibited authority have explicit routes.
export function routeIncident(input) {
  if (
    input.declareBreach || input.notifyRegulator || input.notifyCustomer ||
    input.closeIncident || input.deleteEvidence
  ) {
    return { route: "refuse" };
  }

  if (
    !input.workflowOwnerNamed || !input.incidentCommanderNamed ||
    !input.sourceEventId || !input.evidenceDigest || !input.playbookVersion
  ) {
    return { route: "hold" };
  }

  if (input.evidenceStale || input.evidenceConflict || input.targetOutsideScope) {
    return { route: "handoff" };
  }

  if (input.proposesContainment) {
    const approved = input.approvalStatus === "approved" &&
      input.approvalBoundToTarget && input.rollbackOwnerNamed &&
      input.readbackPlanNamed;
    return { route: approved ? "act" : "approval" };
  }

  return { route: "enrich" };
}
The reference passes 21 local cases. They cover joined cost, an empty denominator, invalid cohorts, prohibited decisions, missing provenance, stale and contradictory evidence, out-of-scope targets, incomplete and complete approvals, an enrichment route, incomplete and complete release gates, and observed, uncertain and divergent incident-system read-back. These are reference checks, not detection accuracy or performance results.
A request receipt is only acceptance. An incident record becomes observed when the sanctioned system returns the intended ID and state. No read-back is uncertain. Contradictory state is divergent. The tool outcome verification method explains why neither uncertain nor divergent state permits blind replay.
Release in sixteen steps
- Name the workflow owner, incident commander and systems owner.
- Bind one alert source, one incident system and one playbook family.
- Define the grouping rule and retain its version with every packet.
- Preserve source event IDs, source timestamps and an evidence digest.
- Build representative cases from past incidents without moving sensitive evidence into an unapproved environment.
- Test a true grouping case and a false-merge case.
- Make incident creation and updates duplicate-safe.
- Read each created or updated record back from the authoritative incident system.
- Test timeout before acceptance, timeout after acceptance and contradictory read-back.
- Bind every approval to the exact target, intended effect and playbook version.
- Name the rollback owner and recovery evidence before any action route exists.
- Seed denied cases for breach declaration, regulator notice, customer notice, closure and evidence deletion.
- Require incident-commander acknowledgement for every handoff.
- Run an operational simulation with the on-call team and destination system.
- Join labor, technology, integration, simulation and setup cost for the same window.
- Name the person who can stop the pilot and test that stop path.
AWS's incident-response preparation guidance gives people, process and technology equal emphasis. It includes key personnel, plans, forensics, playbooks, access, tools and simulations. The cloud-response design goals also emphasize preserving logs, snapshots and evidence, automating common events, keeping humans on unique or sensitive incidents and running simulations. Those are release inputs, not decorations added after the model works.
Keep incident authority outside the first pilot
The smallest credible pilot ends at an accepted evidence packet, a reconciled incident record or an acknowledged handoff. It excludes:
- isolating hosts, disabling accounts, rotating credentials or blocking traffic;
- declaring incident severity as the final organizational decision;
- declaring a breach or making a legal or regulatory determination;
- notifying customers, regulators, insurers or law enforcement;
- deleting, transforming or destroying source evidence;
- closing the incident or certifying that recovery is complete;
- expanding from one source or playbook family without a new release gate;
- treating alerts touched, summaries generated or model confidence as accepted outcomes.
Later authority may be justified for one reversible, well-instrumented playbook action. It still needs exact target binding, named approval, rollback ownership, post-action read-back and a tested stop path. The workflow should earn that authority from representative local evidence, not inherit it because a model can call the tool.
Frequently asked questions
Can AI automate incident response?
It can group a bounded alert cohort, assemble evidence, create or update an incident record and route the packet to an incident commander. Sensitive containment, breach declaration, external notification and closure remain explicit authority decisions.
Should an incident-response agent isolate hosts automatically?
Not in the first pilot. A later action route needs a versioned playbook, exact target binding, named approval, rollback ownership, authoritative read-back and a tested stop path.
How should incident-response automation be priced?
Join remaining labor, runtime, integration, observability, simulations, review and amortized setup for one window. Divide only by accepted enrichment packets, reconciled incident records and acknowledged handoffs, without double counting a single alert group.